|
I am a final-year Ph.D. student at the University of North Carolina at Chapel Hill, advised by Prof. Hongtu Zhu. My research lies at the intersection of Reinforcement Learning and LLM Reasoning, with a focus on addressing real-world challenges in areas such as efficient inference and information retrieval. Seeking full-time opportunities as an AI Researcher or AI/ML Engineer in the Bay Area or North Carolina. |
|
Research Highlights
-
RLVR for Real-world Applications
- Efficient Exploration: Curiosity-Driven Exploration for RLVR training.
- Parallel Reasoning: Parallel-R1, the first RL framework to teach LLMs parallel thinking.
- Information Extraction: R1-RE, pioneer LLM reasoning for OOD Relation Extraction.
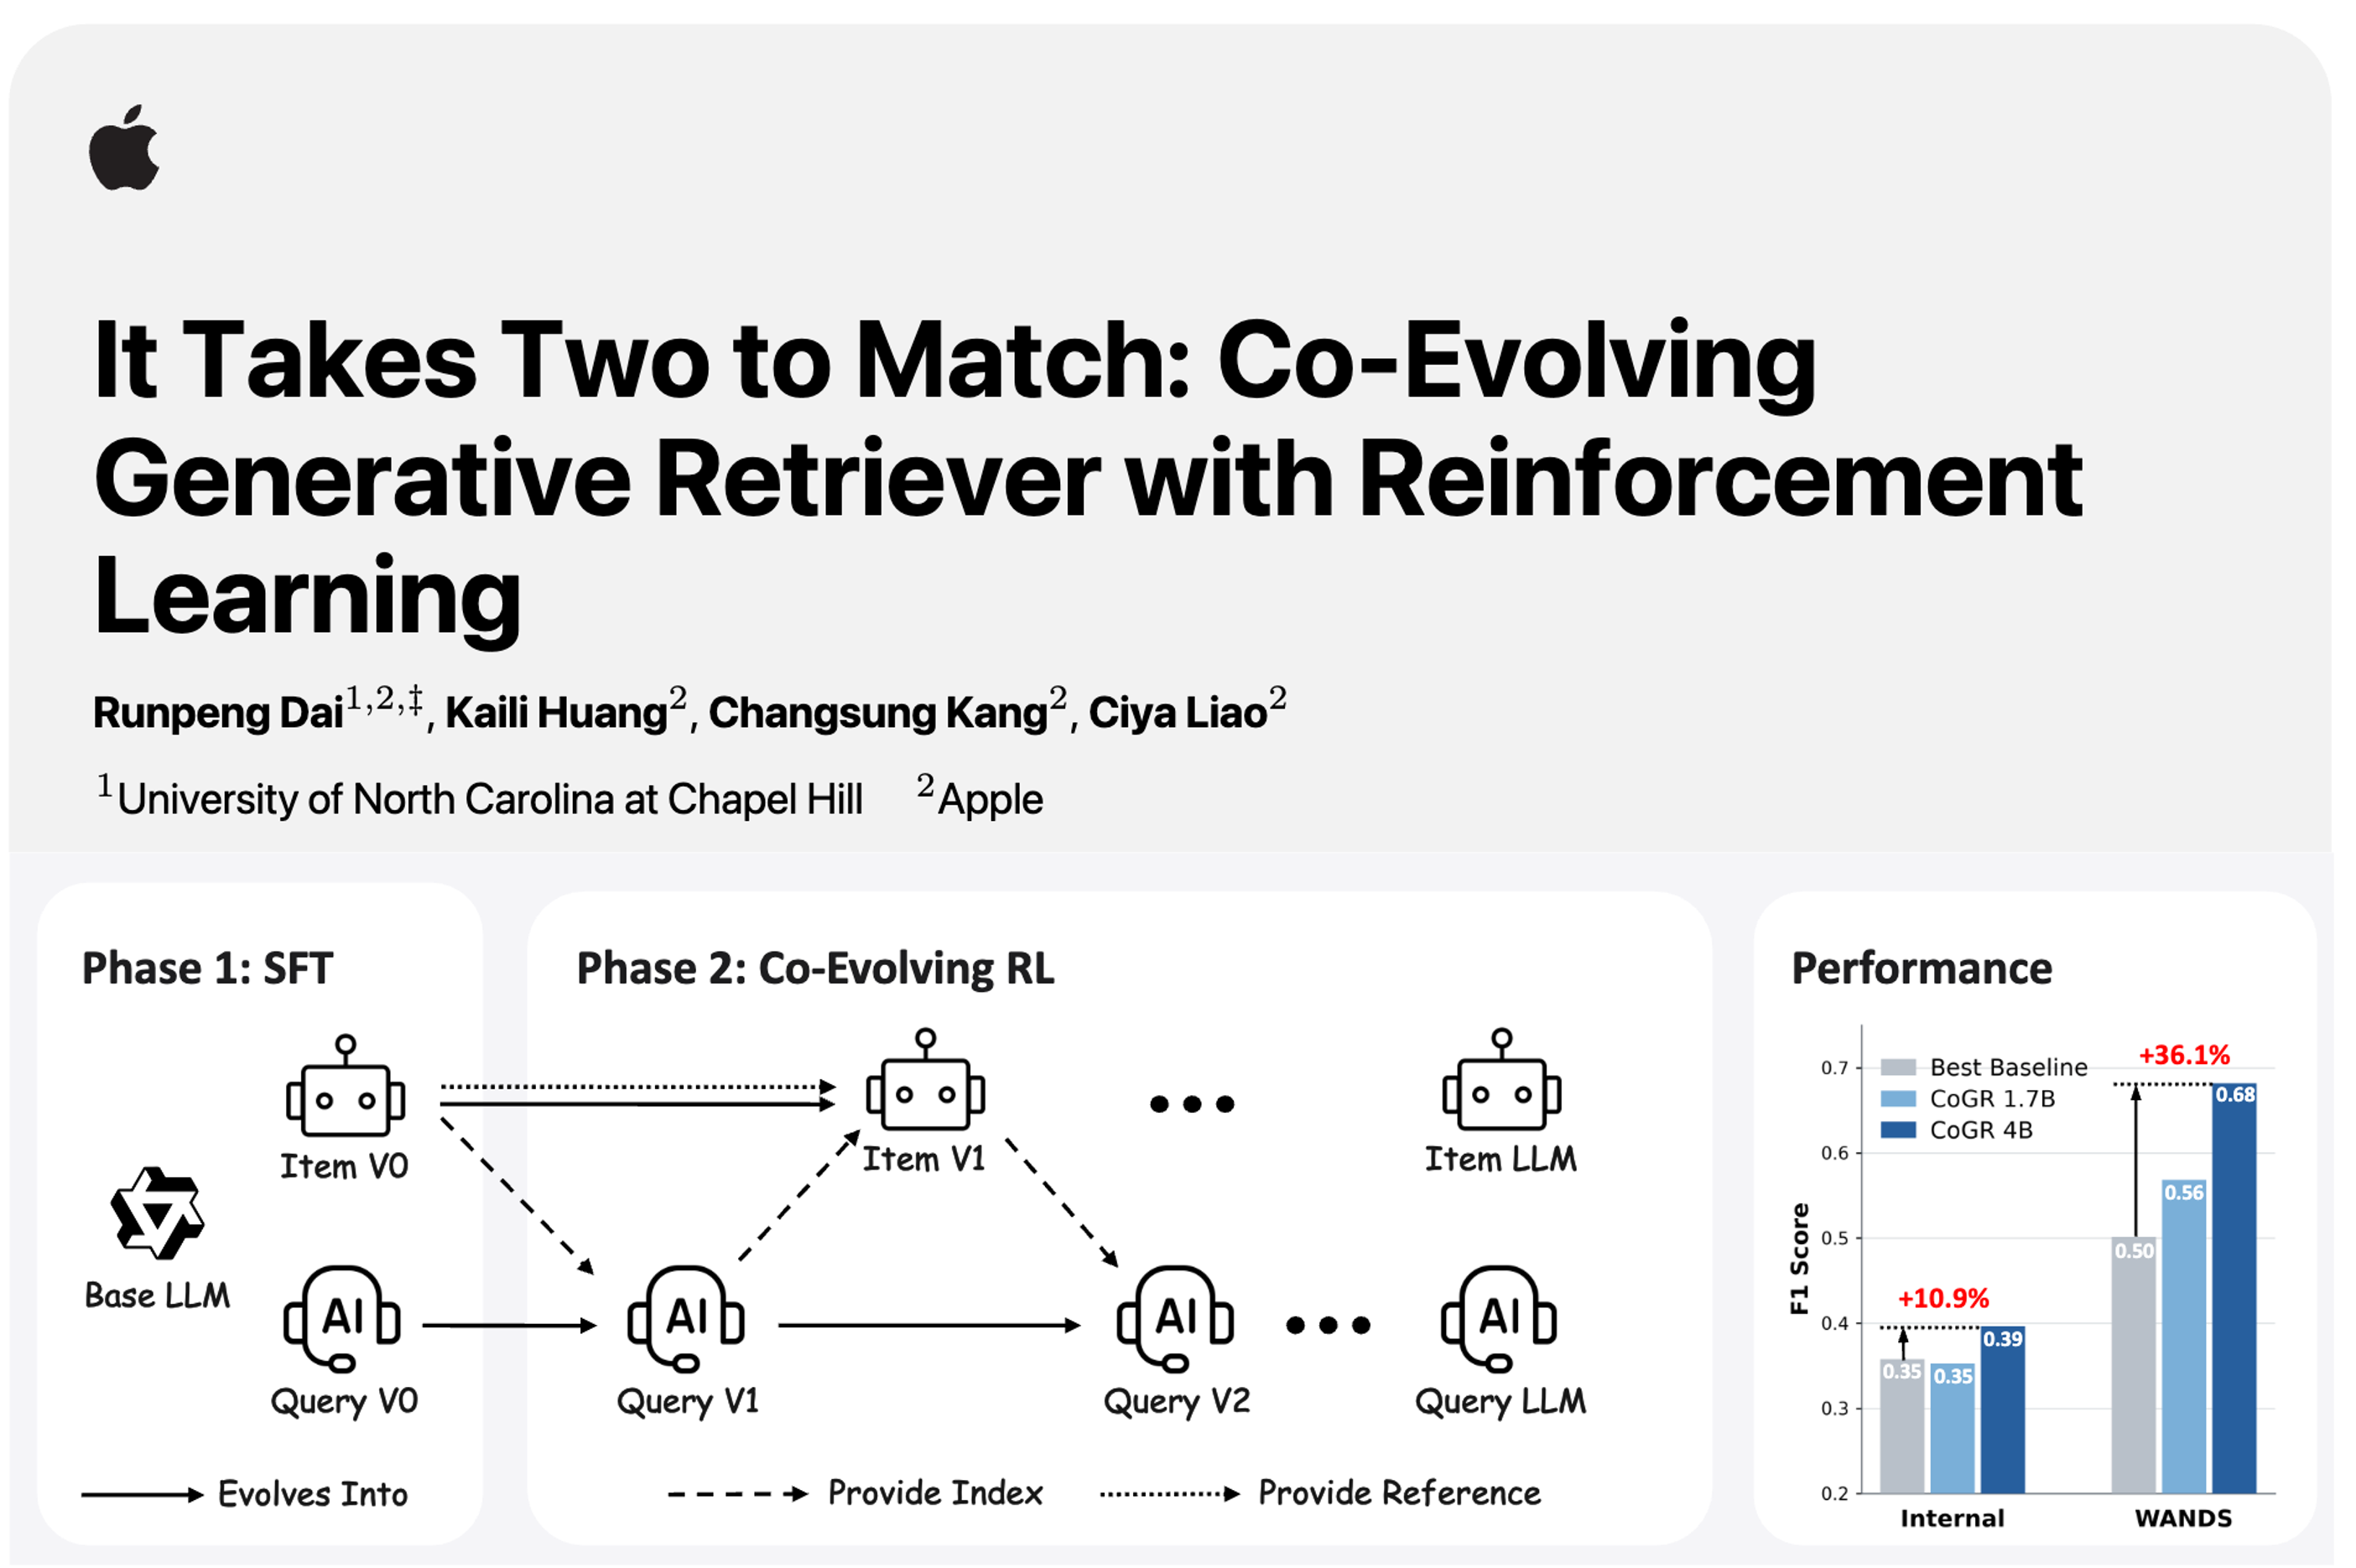
- Information Retrieval: CoGR, co-evolving RL framework for industrial ads retrieval.
-
Efficient Reasoning & Test Time ScalingDeveloping intelligent agents and advanced post-training techniques for next-generation AI systems.
- Adaptive Sampling: RL-Guided Sampling, a small RL controller that guides adaptive sampling for efficient test-time scaling.
- Probing: Parallel-Probe, towards efficient parallel thinking via 2D probing.
Research Experience
- Completed CoGR, a generative retrieval framework that trains a query generator and an item generator to co-evolve via reinforcement learning.
- Applied to internal APP marketplace APP retrieval system.

- Developed CDE, leveraging a model's intrinsic sense of curiosity to guide exploration in RLVR
- Collaborated with fellow interns and colleagues on Parallel-R1 and VOGUE.

- Proposed a transformation-invariant sensitivity measure for LLMs and VLMs.
- Applied the metric to safeguard vulnerable parameters during Quantization and Model Merging.
Selected Publications
|
[Paper] |

|
[Paper] |

|
[Paper] |

|
[Paper] |

|
[Paper] [Code] |

|
[Paper] [Code] |

|
[Paper] [Code][Over 200+ Stars] |

|
[Paper] |

|
[Paper] |

|
[Paper] |

|
[Paper] |
Teaching & Professional Service
| Teaching |
Lecturer of Deep Learning Methods in Advanced Statistical Problems, providing a 2-hour section on LLMs.
[Video P1]
[Video P2]
JSM 2026, ENAR 2026, JSM 2025, ICSA 2024 |
Teaching Assistant of BIOS740 Deep Learning for Biomedical Applications, University of North Carolina at Chapel Hill, Fall 2024, Fall 2025
|
| Professional Service |
| Reviewer of JASA, NeurIPS, AAAI, ICLR, ICML |
| Awards & Honors |
| Graduate Travel Award Recipient, 2026, University of North Carolina at Chapel Hill |
| Gillings Global Health Expendable Scholarship, 2026, University of North Carolina at Chapel Hill |
| LAMBDA Research Grant, 2026 |
| ICLR 2026 Travel Award |
Life
Outside of research, I enjoy fishing both in freshwater and saltwater. My Fishing Photos in Instagram .